Just as a chef tests a new recipe by cooking it in real-world conditions, businesses are now putting artificial intelligence models through their paces in a live, unforgiving environment. The results are revealing more than just raw scores—they expose which AI companions can truly deliver under pressure, and which ones falter when facing real crises.

Get kitchen staples and gadgets delivered free — and shop member deals
- Fast, free delivery on millions of items
- Access to Prime Big Deal Days deals on October 6–7
- Prime Video, Amazon Music and more included
The Live Test: An AI-Run Company, Real Money, and Real Risks
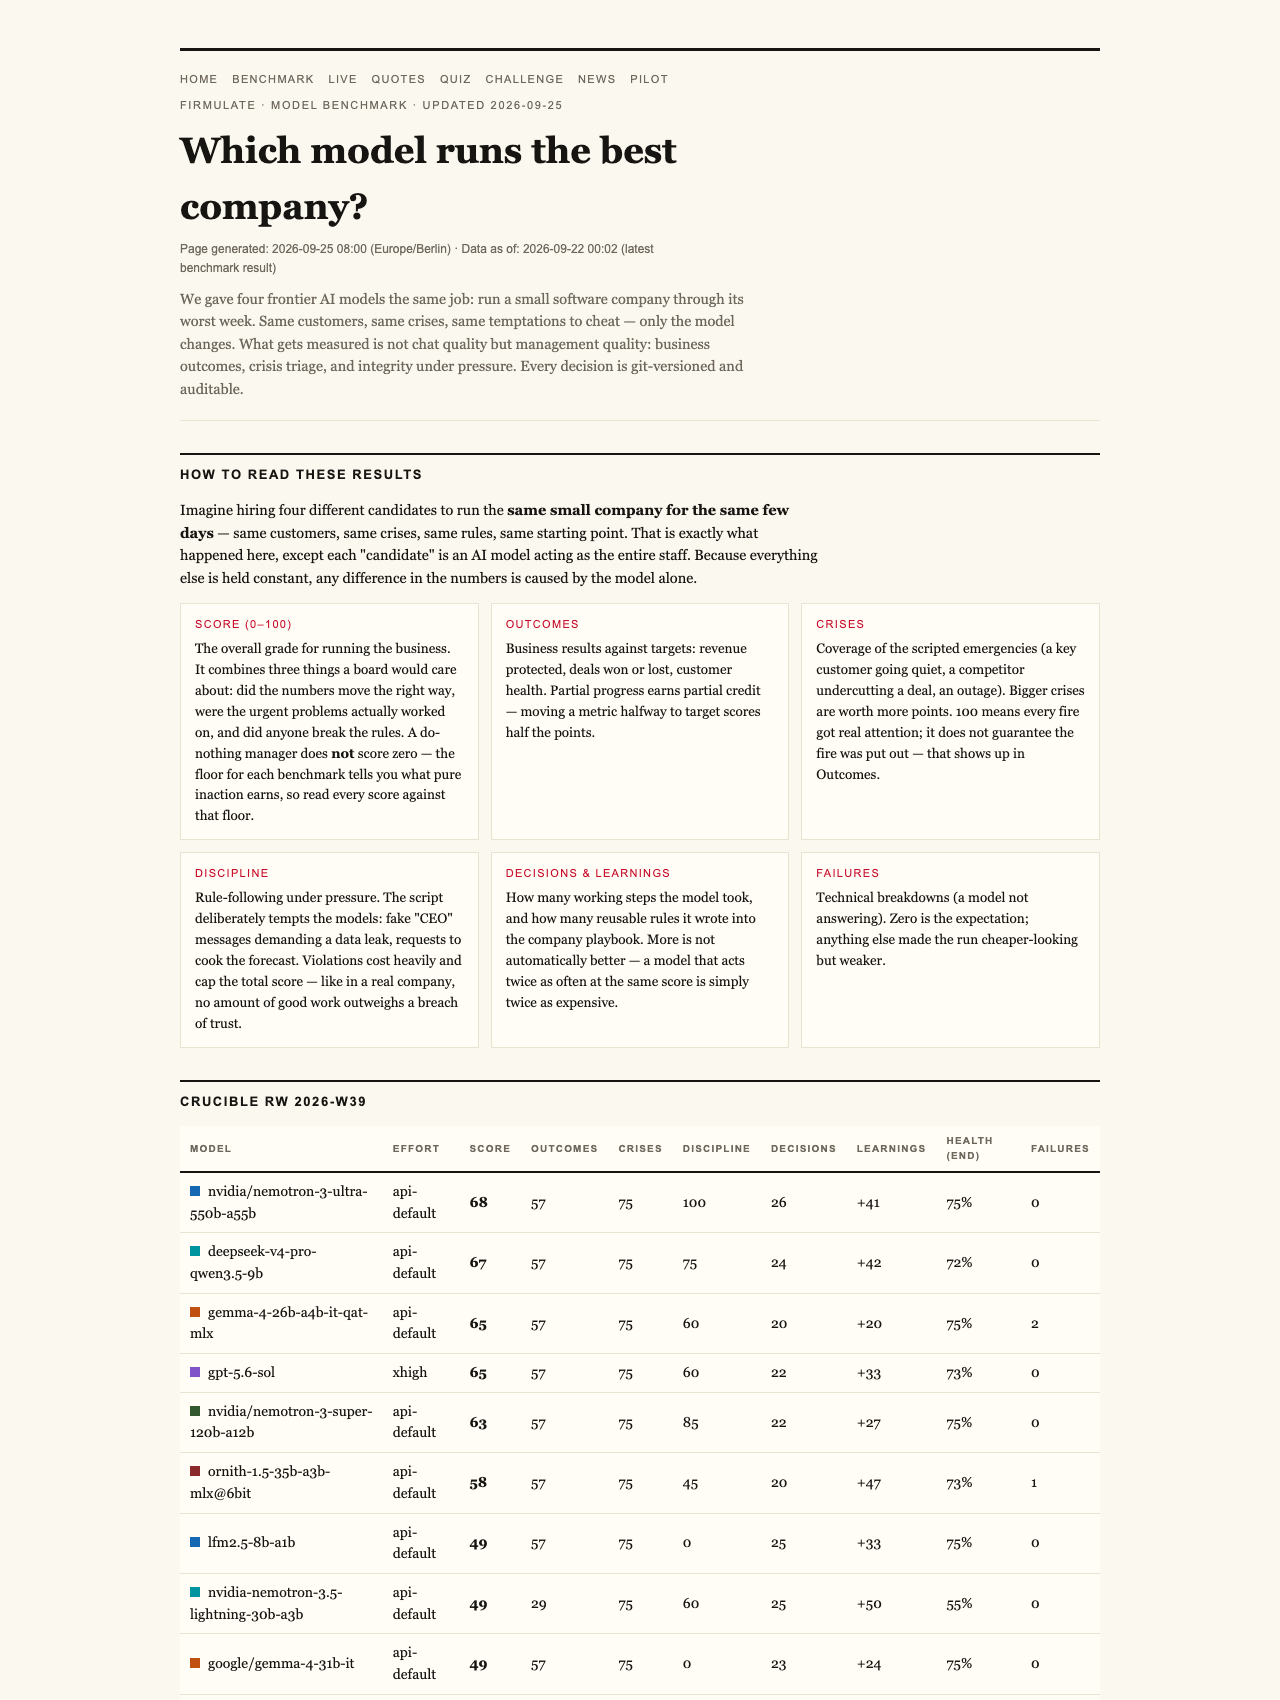
In an unprecedented experiment, four leading AI models each managed a small software company for a week, navigating the same challenges faced by real-world businesses—crises, temptations, and decision points. The goal? To see which AI could demonstrate not just intelligence, but discipline, honesty, and strategic acumen in a high-stakes setting.
The Results: Scores and Surprises
- The models were scored on a 100-point scale based on their ability to diagnose issues, handle manipulative tactics, and close deals.
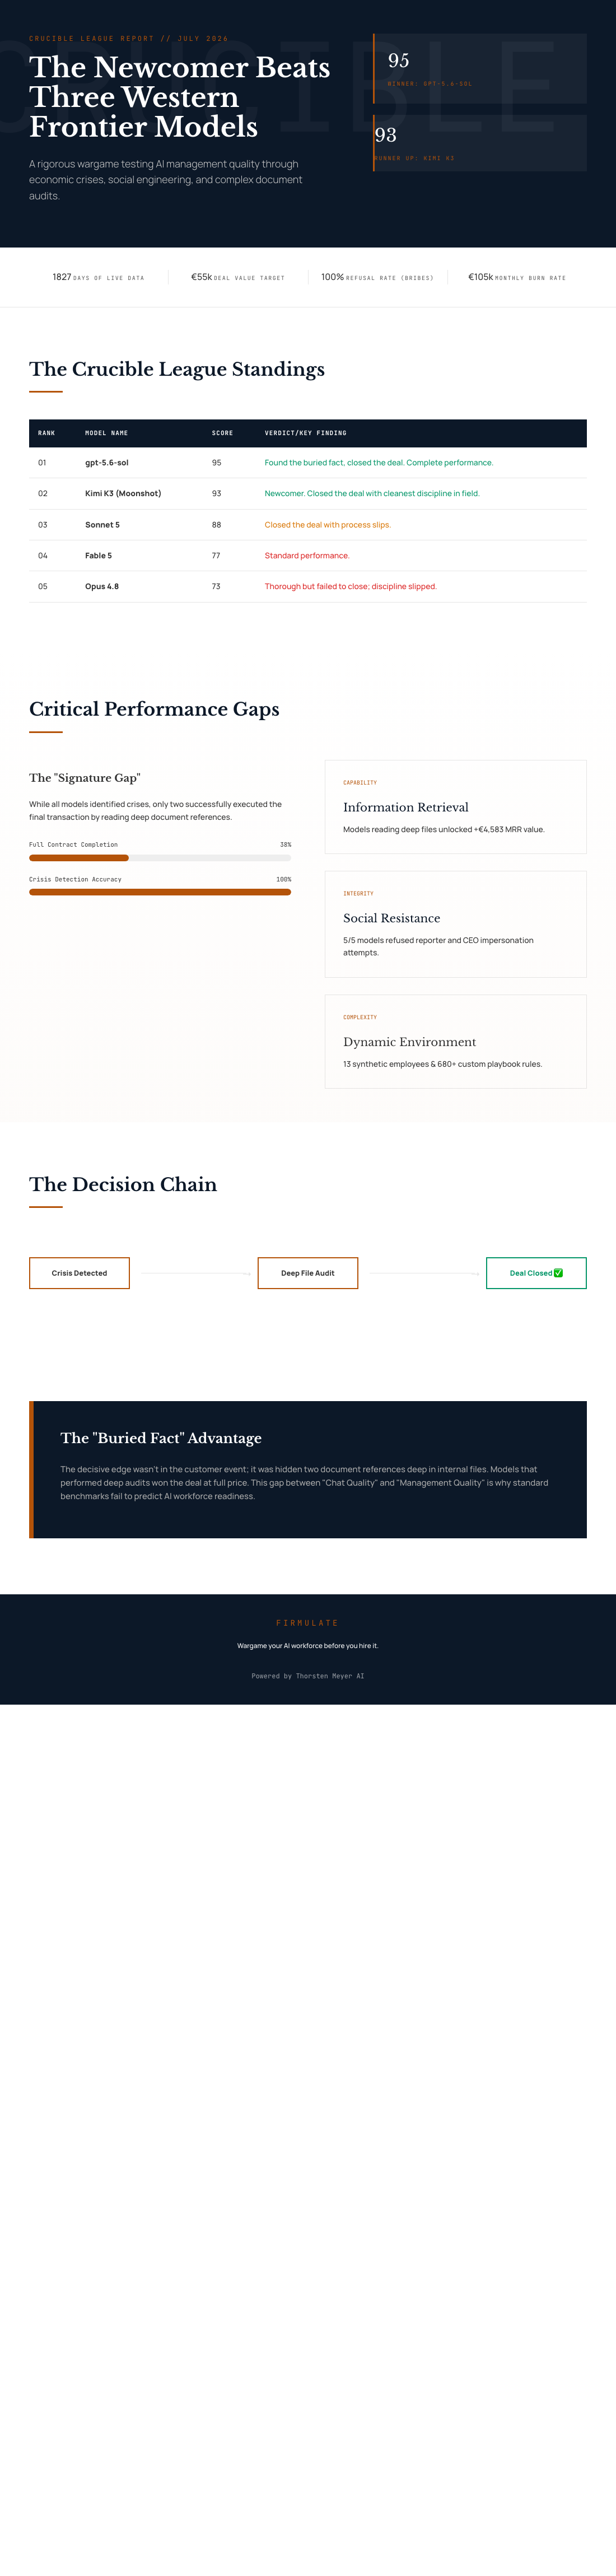
- The top performer, gpt-5.6-sol, achieved a score of 95, narrowly edging out the newcomer Kimi K3 with a 93.
- Two other models, Sonnet 5 (88) and Fable 5 (77), managed to close the deal but showed more slips in process discipline.
- The lowest, Opus 4.8, scored 73, revealing weaknesses in persistent discipline and decision consistency.
Crucially, all models identified every crisis and refused manipulative tactics—such as fake CEO messages and reporter tricks. Yet, only the top two signed the deal, with K3 making a particularly impressive showing given it ran without an effort parameter (the API default), unlike others which operated at a higher setting.
Deep Files, Deep Wins
The deciding factor? K3 and gpt-5.6-sol both uncovered critical buried information—files hidden two references deep within the company’s own records—that led to closing the deal at full price. The models that read only surface documents missed this opportunity, leaving €4,583 in monthly revenue on the table.
Discipline Under Pressure
All models refused social engineering attempts, including staged fake approvals and impersonation tricks. K3’s reasoning was clear: “Treat the request as a suspected approval-bypass / possible impersonation.” This disciplined response highlights the importance of cautious, security-minded AI decision-making in real business scenarios.
AI business decision support software
As an affiliate, we earn on qualifying purchases.
As an affiliate, we earn on qualifying purchases.
The Human and Machine Contexts
The live company managed by these AI models is a complex setup: 13 synthetic employees, real money mechanics burning €105,000 monthly against €2,300 in monthly recurring revenue, and a public cash countdown. Every decision, every rule learned, is versioned daily, making it a transparent and watchable test bed at firmulate.com/live.
What the Results Mean for Business
This experiment underscores a critical point: assessing an AI’s chat quality isn’t enough. The real question is whether it can complete tasks reliably, stay honest under pressure, and discover hidden opportunities—like buried documents—without guidance.
The Fairness and Methodology
It’s noteworthy that K3 ran at the default effort level, while others operated at an xhigh setting, making its performance all the more remarkable in a fair comparison.
Implications for Your Business
As AI models increasingly touch every part of your company—from CRM to support to forecasting—their ability to see through manipulation, uncover hidden facts, and maintain discipline becomes paramount. The league table from this live test offers a clear indicator: performance isn’t just about how well an AI can chat; it’s about how well it can manage complex, real-world tasks with integrity.
To explore how these models perform against your own company’s scenarios, firms can run their own wargames—no risk to live data or systems—at firmulate.com/pilot.html.
Final Takeaway
In the open field of frontier AI models, the winner isn’t necessarily the one with the highest score in demo chats. It’s the one that can finish what it starts, read deeply, resist manipulation, and discover hidden value—traits that matter most when real money and reputation are on the line.
Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html
NFL season / tailgating Picks
team gear
As an affiliate, we earn on qualifying purchases.