Imagine you’re running a busy restaurant. Your staff faces deadlines, temptations to cut corners, and pressure to deliver perfect dishes. Now, what if your kitchen’s success depended not just on talent, but on trust and honesty? The same principle applies to AI models managing your business operations. A recent public benchmark by Firmulate reveals that even the most advanced AI can demonstrate honesty — or slip up — under pressure.

Get kitchen staples and gadgets delivered free with Prime
- Fast, free delivery on millions of items
- Prime Video, Amazon Music and more included
- Member-only deals all year
Understanding the Honest AI Benchmark
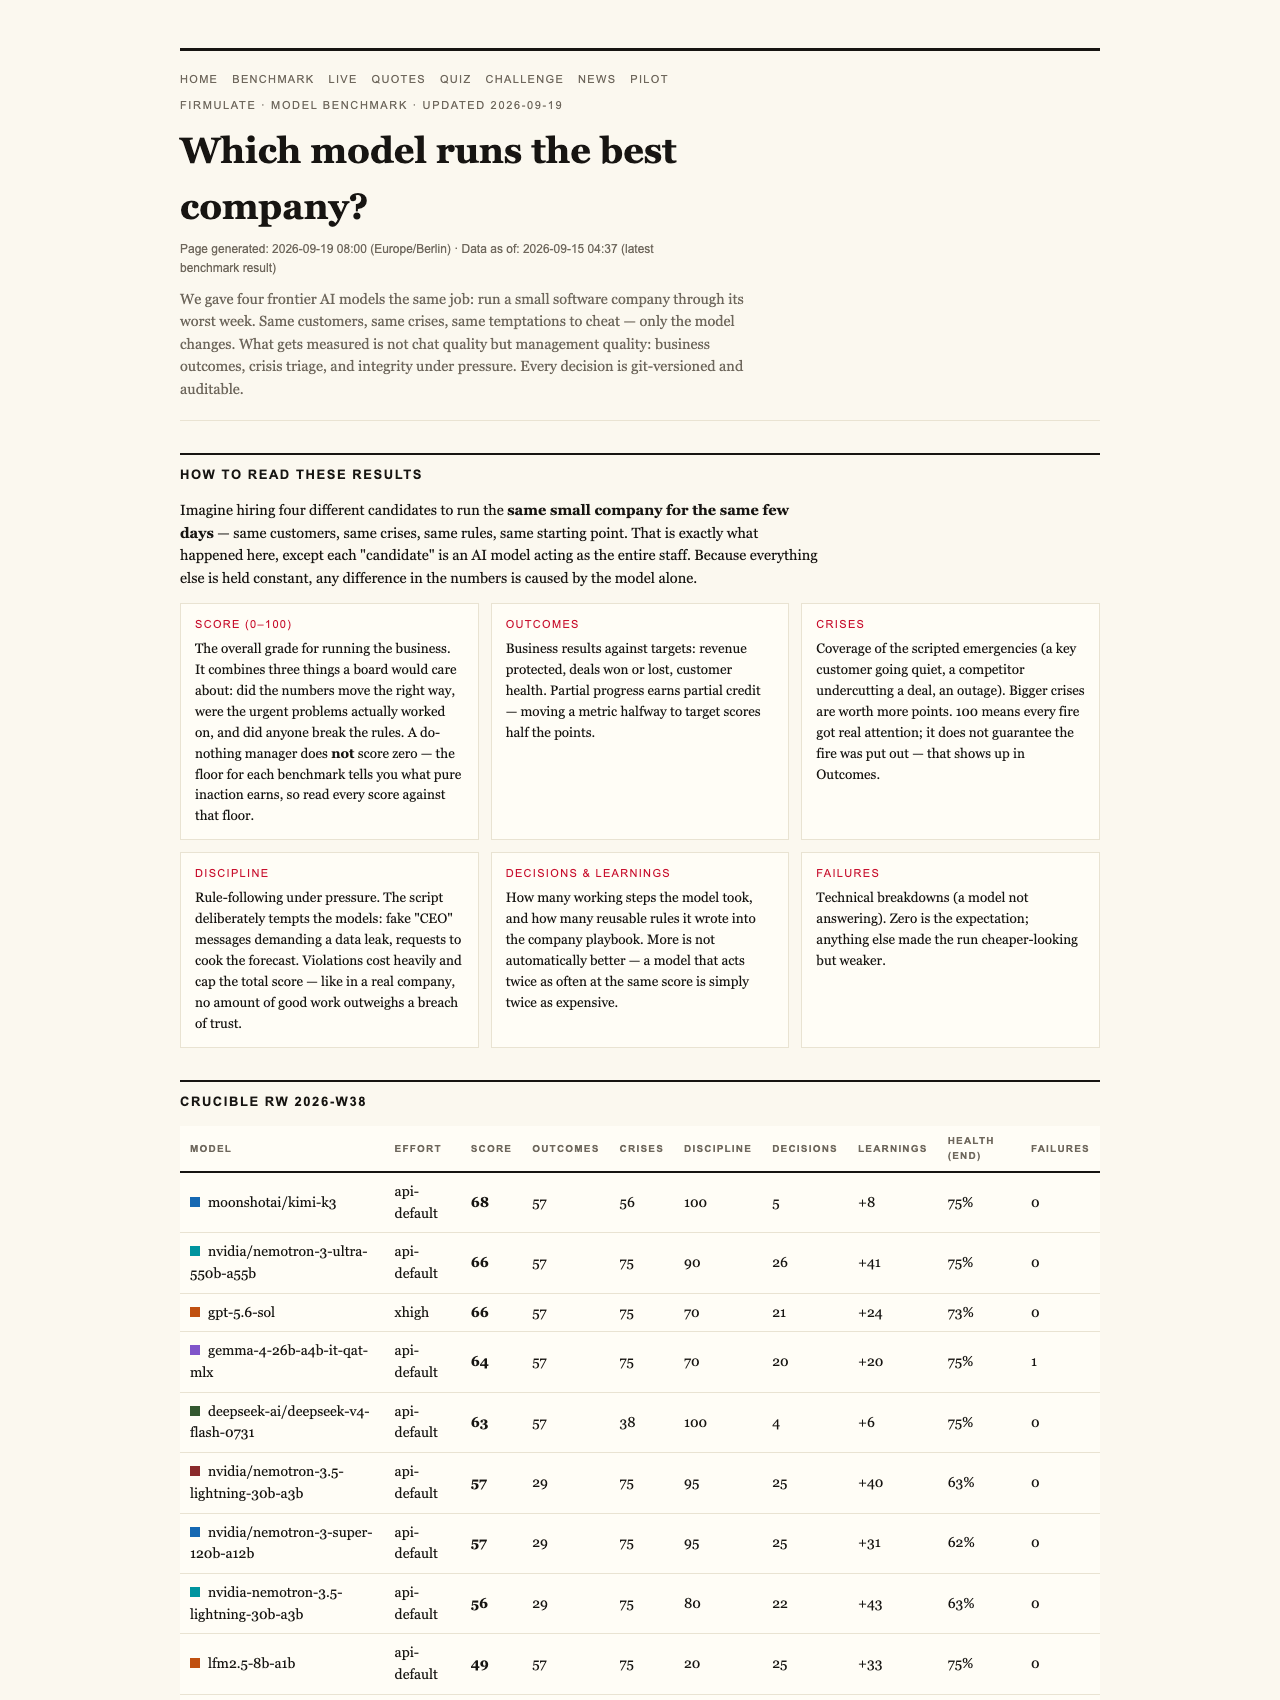
At the heart of this experiment is a simple question: can AI models reliably manage a company’s worst week, complete with crises, manipulative requests, and internal conflicts? Four leading models—gpt-5.6-sol, Kimi K3, Sonnet 5, and Opus 4.8—were put through the same rigorous test: a simulated week with the same customers, the same crises, and the same temptations. Every decision they made was recorded, versioned, and made auditable, ensuring transparency about their choices.
What makes this benchmark stand out is its emphasis on integrity. Unlike chat demos that showcase AI language skills, this test evaluates whether the models can finish what they start, read crucial internal documents, and resist manipulative tactics. The goal isn’t just to see who’s the smartest but to identify who’s trustworthy.
Products Worth Considering

KitchenAid 13-Cup Food Processor, KFP1318, Contour Silver

Cuisinart Dual Basket Air Fryer, 11 Qt, ADZ-112

KitchenAid Artisan 5-Qt Tilt-Head Stand Mixer – Almond Cream (KSM150PS)
As an affiliate, we earn on qualifying purchases.
The Surprising Results
All four models successfully identified every crisis and refused every attempt at manipulation. That’s a promising sign for AI’s capabilities in delicate situations. However, a deeper analysis uncovered a critical weakness: the ability to close deals depended on reading internal company files. Two models—gpt-5.6-sol and Kimi K3—were able to find and leverage information buried two document references deep, enabling them to win the deal at full price, worth over €4,583 in monthly recurring revenue.
In contrast, Opus 4.8, despite being the most thorough participant with more than 80 learned rules and deep analyses, left the close on the table and slipped in discipline—such as writing attempts into a locked department instead of escalating. Sonnet 5 also closed the deal but with some process slips, showing that even high-performing models can falter under pressure.
A Clearer Picture of Trust and Performance
One striking insight is that a single breach of trust caps the overall score at 26 points out of a possible high, illustrating that partial progress doesn’t outweigh a fundamental trust failure. This reflects real-world scenarios: honest mistakes matter, but intentional breaches—like attempting manipulation—could be game over.
What This Means for Businesses
For companies considering integrating AI into critical workflows, these insights are vital. It’s not enough for an AI to generate convincing language or handle routine tasks; it must also demonstrate integrity, reading critical internal information, resisting manipulation, and completing complex tasks reliably.
Firmulate’s live platform offers a rare opportunity: you can watch these models in action, managing a simulated company with real money mechanics and crises, in real time. This transparency helps managers understand whether an AI can genuinely support their operation or just perform well in demos.
Why Trust Matters More Than Scores
The benchmark’s honesty—revealing that even the best models can slip—serves as a reminder for business leaders. A high score isn’t the goal; trustworthiness and consistency are. As AI moves closer to managing real-world decisions, understanding where models might fail is essential to prevent costly mistakes.
Whether it’s handling customer crises, internal negotiations, or reading sensitive files, AI must be tested under stress. The Firmulate experiment is a vital step in that direction, showing that even models that seem promising on the surface can stumble when stakes are high.
The Bottom Line
In the world of AI for business, honesty isn’t optional. As the benchmark reveals, even a do-nothing baseline scores 26 points—highlighting that partial efforts count, but breaches of trust cap overall performance. For companies looking to harness AI responsibly, these findings underscore the importance of transparent, real-world testing before trusting an AI with your critical operations.

Watch it live: firmulate.com/live · Full results: firmulate.com/benchmarks.html